What Happened
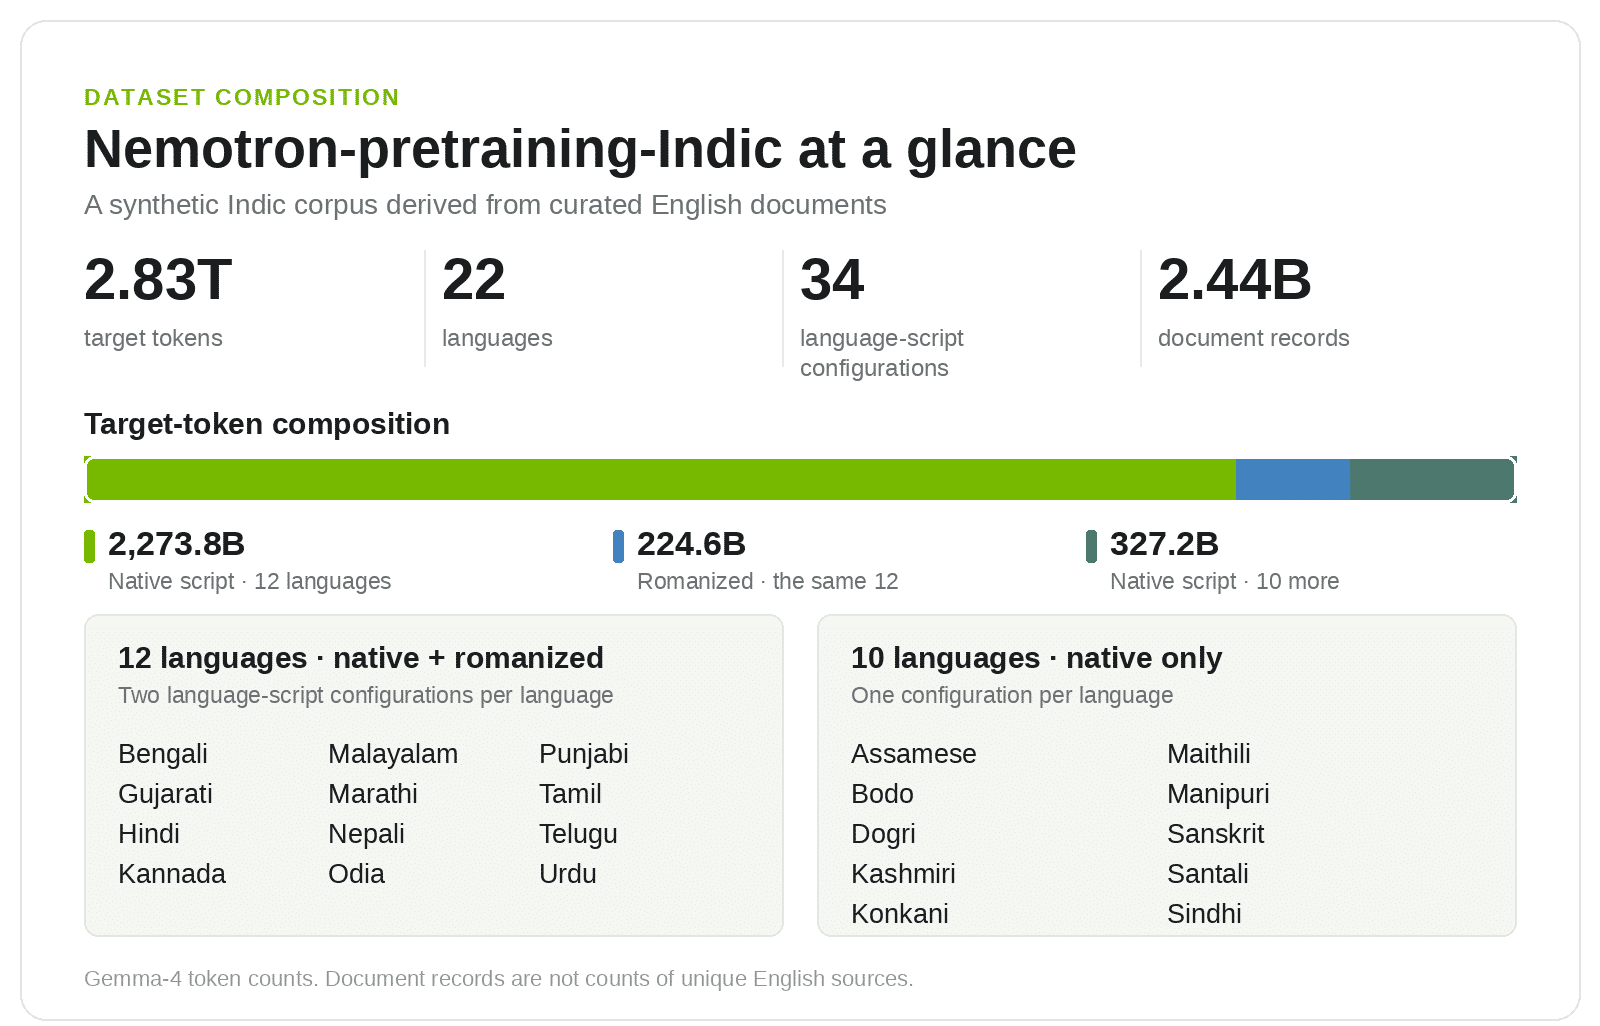
NVIDIA published a post on the Hugging Face blog about scaling pretraining for Indic languages. According to the post's title, the work involved 2.8 trillion tokens and an open data generation pipeline.
The Key Details
- Organization: NVIDIA, via the Hugging Face blog
- Topic: Scaling Indic pretraining
- Scale: 2.8 trillion tokens
- Component described: An open data generation pipeline
- Published: October 16, 2026
What Remains Unknown
The supplied material does not include details on:
- Which Indic languages are covered
- What models, datasets, or code were released
- Whether the pipeline or outputs are available for public use
- Technical specifications or performance results
- Any quotes or statements from NVIDIA researchers
Why It Matters
Efforts to train AI models on very large collections of text in Indic languages could support more capable language technologies for speakers of those languages. An open data generation pipeline could, in principle, allow other researchers to replicate or extend the work. Because the supplied information is limited to the blog post title, the actual scope and availability of the release cannot be confirmed from this material alone.
VANTIX Takeaway
NVIDIA is working on large-scale pretraining for Indic languages using 2.8 trillion tokens and an open data pipeline, but the available information does not yet say what was released, which languages are included, or how readers can access it.


